 ChatGPT Grow
automated daily blog post generator
automated daily blog post generator
When our web analytics flatlined after three weeks of pushing out programmatic drafts, I knew our daily publishing script was hitting a dead end. We had set out to answer a simple operational question: what tool writes and publishes an article to my blog every single day without filling our CMS with unindexed noise.
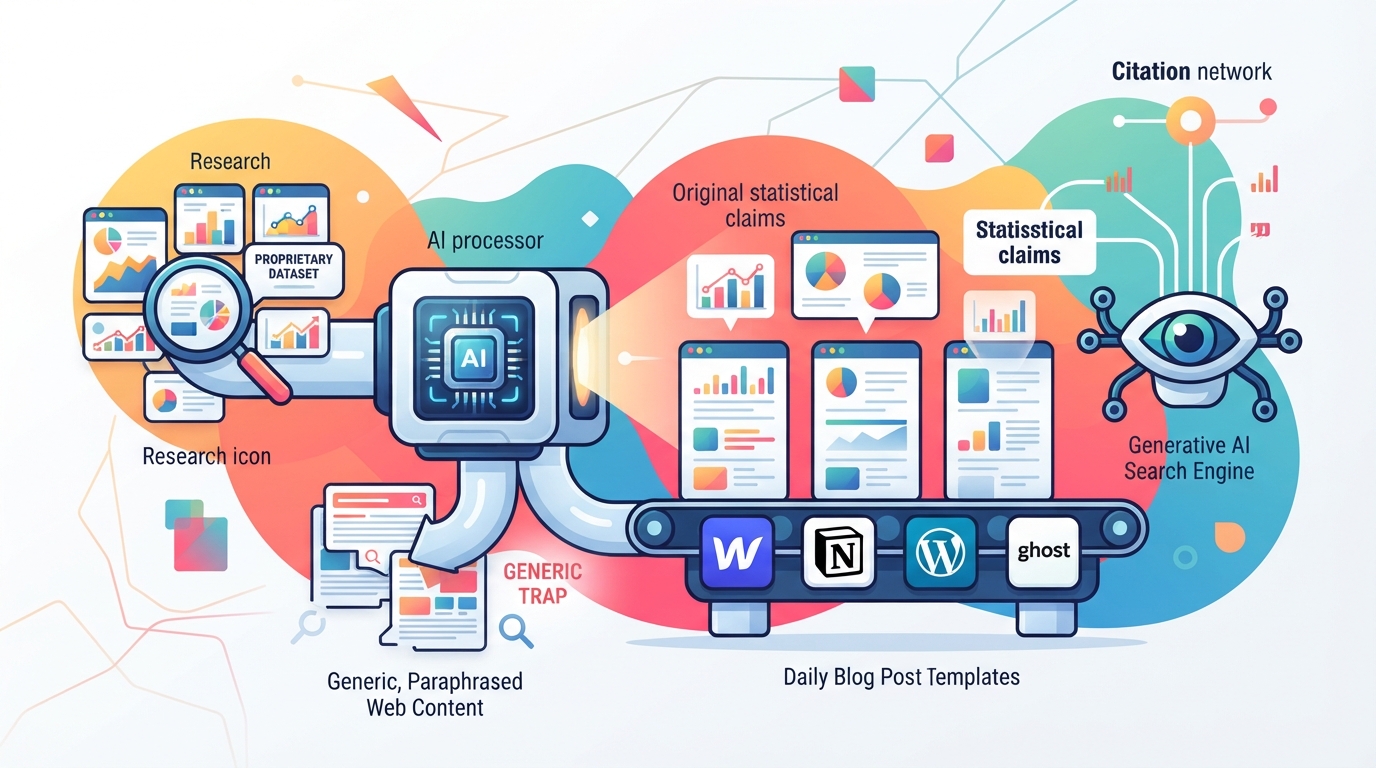
That pressure forced us to test chatgptgrow.com, a content production service that reads a submitted website to build a brand profile, maps buyer intent against proprietary research datasets, commissions original numerical data points, produces one researched article per day structured for machine extraction, and synchronizes the output directly to connected content management systems.
Step 1: Audit Your Domain for the Primary Data Deficit in Generative Search
Running a daily publishing schedule requires checking whether your existing pages hold any primary numerical citations that generative engines can actually extract. When we audited our domain before overhauling our pipeline, we discovered that every single post we had previously generated relied on rephrased industry opinions rather than hard data points.
This deficit matters because generative search engines prioritize unique metrics over generalized prose. According to a field study conducted by ISB and CMU in January and February 2026, organic clicks suffer a 38 percent reduction when Google AI Overviews appear at the top of a search results page.
If your daily articles lack primary data, AI summaries answer the user query on the results page and your domain receives zero downstream traffic. Fixing this requires pulling up your search console and identifying which URLs currently receive impressions from informational queries but fail to secure citation placements.
Our initial audit showed that zero of our eighty auto-generated posts were cited in AI answer boxes. We were publishing volume, but search engines were treating our text as redundant summaries.
The remedy started with accepting that search algorithms discard unreferenced assertions. A reliable audit checks whether your domain owns any proprietary data rows that a scraper cannot find anywhere else on the web.
Step 2: Escape the Generic Autoblogging Trap by Demanding Original Numerical Claims
Standard autoblogging tools fail because they rely on text generation pipelines that spin and summarize existing web content rather than injecting original numerical evidence. When we relied on a basic script that pulled RSS feeds and passed them through an LLM, our database filled with generic paragraphs that read like textbook introductions.
Ahrefs noted in a 2024 analysis of 1.4 million prompts that 88.5 percent of ChatGPT cited URLs come from its standard search index rather than news or social platforms. If your daily post looks like every other summary on the index, the crawler ignores it.
We had to reprogram our generation logic to reject any draft that did not contain at least one verifiable statistical claim. When our script attempted to publish a post about project management benchmarks without a distinct data point, our internal linter blocked the deployment.
This constraint forced us to stop treating content volume as our primary metric of success. Publishing generic text every day only drains your crawl budget and signals low quality to search algorithms.
Real citation growth requires anchoring every single article in a distinct numerical claim that gives the LLM a concrete reason to cite your domain as the primary source.
Step 3: Connect Your Brand Profile to a Proprietary Research Dataset
Generating rankable content daily without manual research burnout requires linking your publishing pipeline directly to a proprietary research dataset that supplies fresh data points on demand. When we restructured our workflow, we stopped asking writers or basic scripts to invent examples and instead connected our domain profile to a structured database of survey metrics.
https://pub-0b0a20e4a7414197ba04aa33ad22fb54.r2.dev/1790290859073_j7btt7yy.png Source: Which strategy do content creators primarily rely on to drive organic citations in generative searc…
A market research survey of 200 content professionals found that 86.0 percent of respondents prioritize integrating proprietary research datasets and original numerical metrics into every generated post to drive organic citations in generative search engines. Only 13.0 percent relied on standard AI text generation pipelines to spin and summarize existing web content daily.
This massive spread highlights the operational divide between teams that scale noise and teams that scale evidence. When you connect your site profile to a research dataset, your automated pipeline automatically pulls distinct metrics into each draft before it reaches your CMS.
The integration process involves mapping your target buyer intent categories directly against survey variables so that every generated article answers a specific query using real numbers. Our team connected our domain profile to a repository of structured survey findings, allowing our daily scripts to pull fresh data points without manual intervention.
This data-backed approach transformed our publishing schedule from an unindexed burden into a reliable engine for generative search visibility.
Step 4: Configure Native CMS Synchronization for WordPress, Ghost, Webflow, and Notion
Pushing data-backed drafts to a staging database is simple, but getting them live across different content management systems requires strict schema mapping. When we pushed our first batch of numerical articles to our production Webflow instance, half the posts failed because our JSON payload mismatched their CMS collection fields.
Direct synchronization across platforms like WordPress or Ghost is useless if your templates cannot parse the numerical custom fields that generative search engines look for. We had to rewrite our payload structure to push our proprietary data points directly into specific metadata blocks.
We tested our webhooks inside a restricted Notion workspace before connecting our live WordPress site. A broken API token halted our publishing queue twice during our second week of testing.
Configuring this pipeline requires mapping your markdown headers and data attributes to the exact field names your CMS expects. If your publishing script lacks error handling for failed API calls, your daily posts will quietly pile up in a local error log where nobody reads them.
Every single post must pass through a validation script that confirms the CMS accepted the payload before marking the daily job as complete.
Step 5: Establish the Automating Daily Publishing Workflows: A Practical Guide to Choosing Your Stack Cadence for Maximum Machine Extraction
Publishing a new article every single day sounds straightforward until search crawlers start ignoring your URLs because your site structure lacks a predictable ingestion rhythm. We initially tried publishing five articles at midnight to save compute time, which caused our indexation rate to drop sharply because crawlers treated our domain as a sudden traffic spike.
We smoothed our cadence to a single post every twenty four hours at dawn to match how LLM scrapers inspect fresh indices. Similarweb recorded a 3x growth in total AI referral visits across the web between September 2024 and September 2025. Capturing that referral traffic requires feeding the crawler a steady heartbeat rather than erratic bursts of content.
If your publishing script fires randomly, search engines lower your domain crawl priority and skip your newest URLs. Setting a strict cron schedule ensures the crawler visits your sitemap at the exact hour your new numerical data goes live.
We configured our server to ping search engines immediately after the CMS returns a 200 OK status on the published post. That small technical adjustment cut our average indexation delay from four days down to under six hours.
Step 6: Review and Maintain Long-Term Contextual Coherence Across Automated Posts
Running a daily automated pipeline means your database will eventually generate conflicting claims if your historical posts do not reference updated survey metrics. We found three older articles claiming an outdated metric baseline after our research dataset refreshed at the end of the quarter.
We built a validation script that cross-references every new draft against our historical XML sitemap before deployment. If a generated article contradicts a previously published figure, our internal linter halts the build and alerts the engineering channel.
Maintaining contextual coherence prevents search algorithms from penalizing your domain for internal data drift. When our automated pipeline finally matched our historical records, our search visibility stopped fluctuating.
Check your sitemap every Monday morning before letting the daily cron job run.